
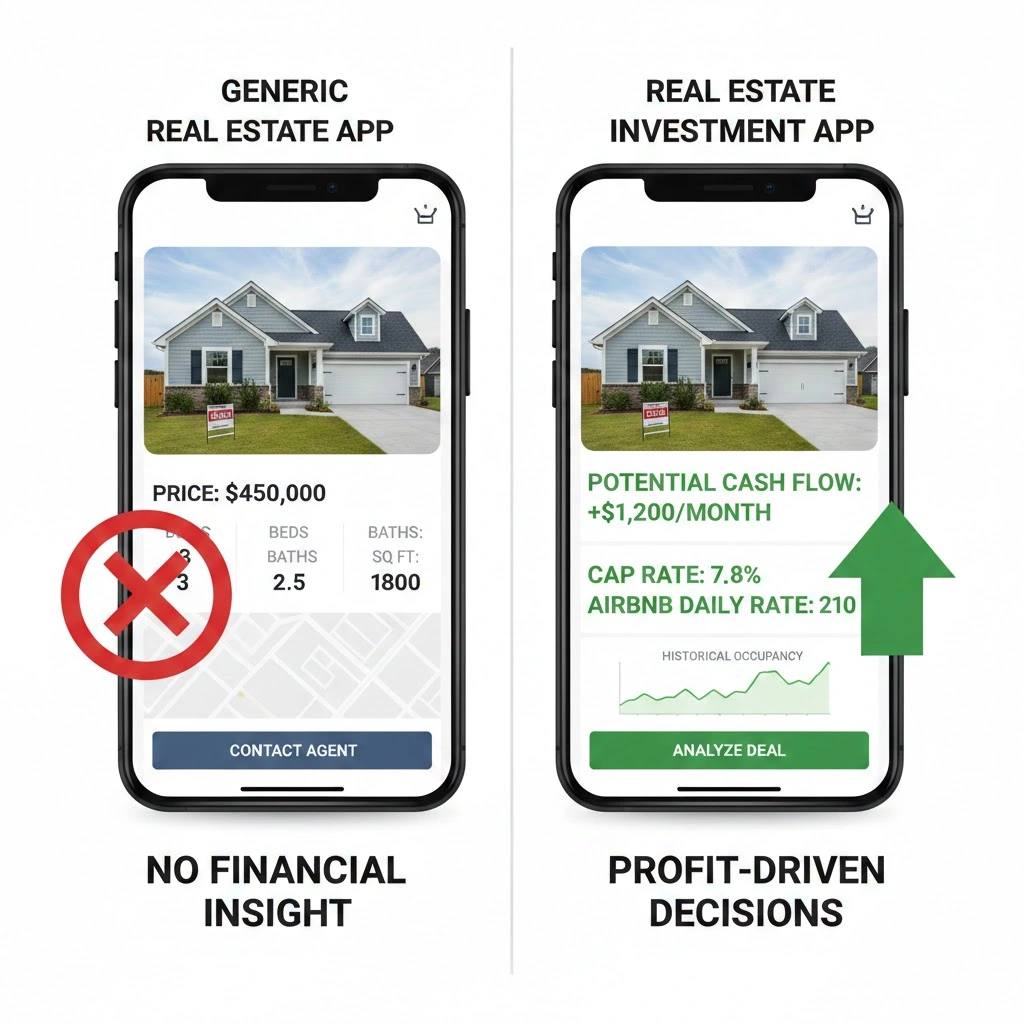
The real estate market is undergoing a significant transformation, marking the end of the era dominated by generic home search applications. For the past decade, the industry’s digital landscape was primarily defined by platforms offering a straightforward display of property photos and prices. However, the current market dynamics are increasingly driven by investors rather than solely by homebuyers. These sophisticated users require more than just a property search engine; they demand a decision engine capable of sophisticated analysis and predictive insights. This fundamental pivot from mere "search" to in-depth "analysis" presents a substantial opportunity for forward-thinking founders. By developing niche investment platforms, entrepreneurs can tap into a high-value audience willing to pay for actionable data, moving beyond the free browsing model that characterized the previous decade. This guide serves as a blueprint for constructing scalable and data-driven real estate investment applications, detailing product strategy, technical architecture, and effective monetization models.
The Strategic Pivot: Why Investment Grade Wins in PropTech
The majority of real estate technology startups often falter by attempting to compete directly with established giants like Zillow on the sheer volume of listings. This is a strategically untenable position, as established players possess extensive Multiple Listing Service (MLS) contracts and substantial funding. Instead, successful PropTech ventures are carving out a competitive edge by focusing on financial intelligence. While a generic app might present a three-bedroom house for $450,000, an investment-grade platform will highlight the same property with a 7.8% Capitalization Rate (Cap Rate) and an estimated $3,200 in monthly Airbnb revenue potential. The objective shifts from merely helping users find a house to empowering them to underwrite an asset effectively. This transformation redefines the backend infrastructure from a passive display of information into an active tool for comprehensive financial analysis.
Core Features for an Investor-Centric Platform
To build an application that resonates with real estate investors, it is imperative to move beyond rudimentary filters like the number of bedrooms and bathrooms. The core features must address the paramount question: "Will this property generate a profit?"
ROI-Driven Search Capabilities
Investors do not typically search by school district; their primary consideration is yield. Consequently, the application must incorporate filters that enable users to discover properties based on their financial performance. This includes the ability to sort and filter by metrics such as Cap Rate, Cash-on-Cash Return, and Projected Occupancy Rates. This approach inverts the traditional search experience. Instead of starting with a desired location and hoping to find a suitable deal, users can begin with a profit goal and then identify locations that align with that objective.
Interactive Heatmaps for Visual Intelligence
The sheer density of data in real estate can be overwhelming, rendering a list of hundreds of properties difficult for human comprehension. Visual intelligence offers a solution through interactive heatmaps. These tools are designed to visualize "Investable Corridors" by overlaying profitability metrics onto a geographical map. This allows users to instantly identify neighborhoods with the highest Airbnb revenue potential or the lowest price-to-rent ratios. This visual discovery layer often serves as the initial point of engagement for new users.
The Deal Analyzer: A Retention Hook
The Deal Analyzer is a critical feature for user retention. Once an investor identifies a potential property, they need the tools to perform detailed financial calculations. A dynamic calculator that allows users to toggle between Traditional Rental and Airbnb strategies enables them to compare which approach yields a superior return. The key to an effective analyzer lies in its customization. Instead of relying on static defaults, users should be empowered to input their own mortgage rates, management fees, and down payment percentages to observe how the Cash-on-Cash return fluctuates based on their individual financial situation.
The Data Ecosystem: Understanding the Technological Stack
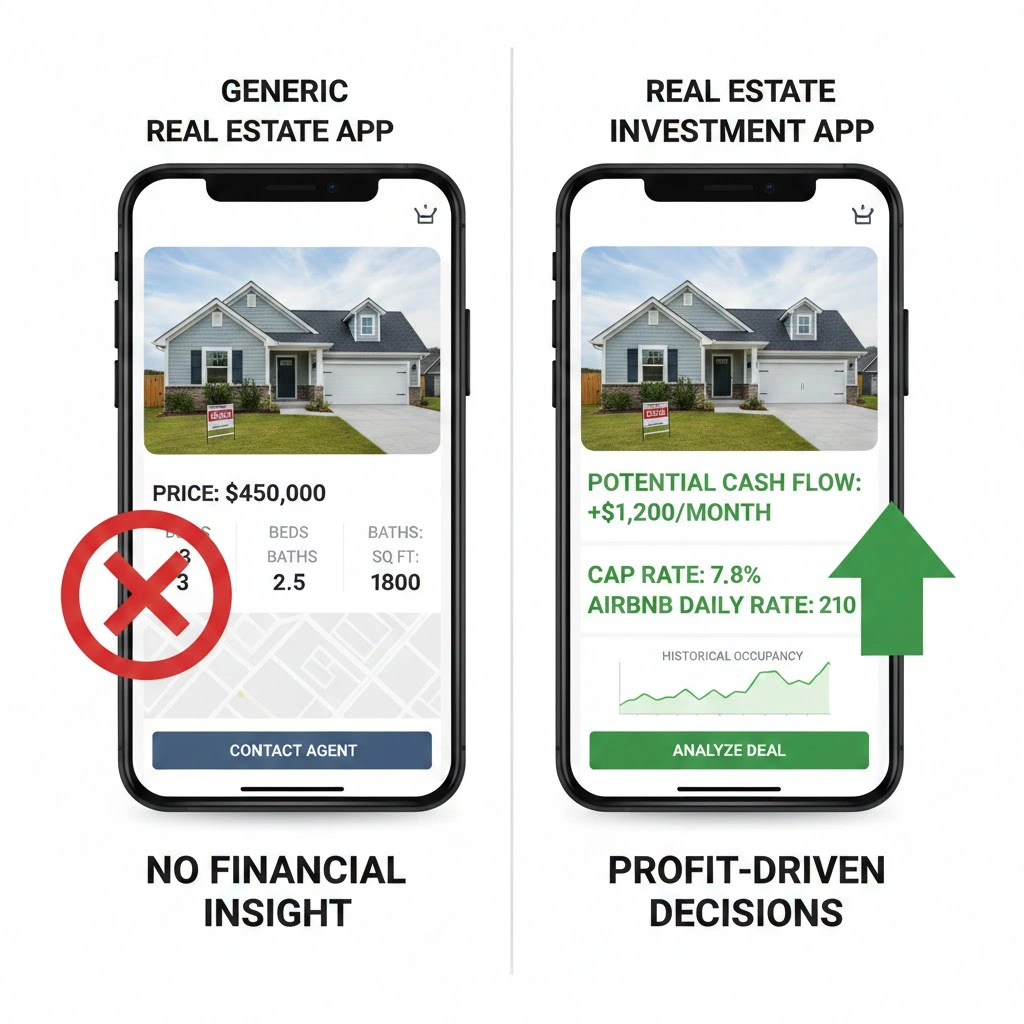
Before any lines of code are written, a thorough understanding of the data landscape is essential. Many founders mistakenly assume that all real estate data is uniform. This is a critical oversight. A modern real estate application is, in essence, a stack composed of three distinct types of Application Programming Interfaces (APIs):
Type A: The Visual Layer
These are foundational APIs, such as Google Maps or Mapbox, which are indispensable for displaying property locations and providing street-level views. However, their utility diminishes when it comes to assessing property value. While they can indicate proximity to amenities like parks, they cannot quantify how such proximity might influence rental yield.
Type B: The Inventory Layer
This layer provides the raw listing data, including addresses, square footage, and asking prices. While crucial, this information is often insufficient for investors. It confirms the existence of a property but does not offer insights into its financial viability. Relying solely on this layer necessitates the development of extensive internal teams dedicated to data cleaning and normalization.
Type C: The Intelligence Layer
This is the often-missing link where a significant percentage of real estate apps fall short. To construct an investment platform, access to pre-calculated financial metrics is paramount. This includes data on rental comparables, expense ratios, and occupancy rates for individual properties. Developing this dataset from scratch can consume years of engineering effort. Many founders find themselves stalled at this stage, possessing mapping and listing data but lacking the critical investment logic.
The Master Architecture: A Top-to-Bottom View
To construct a high-performance real estate investment engine, a departure from the conventional client-server model is necessary. A production-ready architecture requires a three-tiered approach that effectively separates raw data ingestion from proprietary investment logic. This structure ensures that the application functions not merely as a data viewer but as a sophisticated financial analysis tool.
Tier 1: The Ingestion Tier (Data Sourcing)
This forms the foundational layer of the technology stack. Instead of developing fragile web scrapers, data is ingested through pre-normalized APIs. This approach streamlines data acquisition and ensures greater reliability and accuracy.
Tier 2: The Logic Engine Tier (The Secret Sauce)
This constitutes the middle-layer service where proprietary value is added. It acts as an intermediary between the APIs and the user interface, performing the crucial "user-context overlay." This tier takes baseline API data and recalculates it based on user-specific inputs, such as financing preferences and investment goals.
Tier 3: The Presentation Tier (The User Interface)
This is the uppermost layer of the stack, where the product vision is brought to life for the end-user. It is responsible for displaying the analyzed data and facilitating user interaction in an intuitive and engaging manner.
The Request Lifecycle: From User Click to Financial Insight
To comprehend the intricate interaction between these tiers in a live environment, consider the procedural execution flow of a single user session. This sequence of events, akin to climbing a ladder, transforms raw data into actionable financial insights:
- User Interaction: A user initiates an action, such as searching for properties in a specific area or analyzing a particular listing.
- API Request: The presentation tier formulates a request to the appropriate API endpoints in the ingestion tier, seeking the necessary data.
- Data Ingestion: The ingestion tier retrieves raw data from various sources, including market benchmarks, property details, and potentially historical performance metrics.
- Data Processing & Augmentation: The logic engine tier receives the ingested data. It then applies user-specific parameters (e.g., financing options, tax implications) to recalculate and personalize the financial projections.
- Analysis & Insight Generation: The logic engine performs complex financial modeling, generating key performance indicators and risk assessments.
- Data Presentation: The presentation tier receives the processed and analyzed data from the logic engine and displays it to the user in a clear, organized, and visually appealing format, often incorporating charts, graphs, and interactive elements.
The Architecture Solution: Leveraging Infrastructure-Grade APIs
Historically, the barrier to entry for developing investment-grade real estate applications was the formidable data pipeline. This typically involved a dedicated team of data engineers responsible for scraping websites, cleaning addresses, and merging duplicate records. Today, this entire hurdle can be circumvented by utilizing infrastructure-grade APIs that manage the critical "Intelligence Layer" on behalf of the developer.
To illustrate a streamlined development process, the Mashvisor API serves as a reference implementation. This API was selected due to its unique capability to integrate both the "Inventory Layer" and the "Intelligence Layer" seamlessly. It provides pre-calculated investment metrics, such as Cap Rate and Cash-on-Cash Return, which are fundamental to the proposed architectural design.
Accelerating Development with Data APIs
A robust backend architecture should be segmented into three distinct tiers of data ingestion to ensure the application is fast, accurate, and scalable.
Tier 1: The Market Benchmark Layer
Before a user evaluates a specific property, they often assess the broader market. Constructing a backend system that aggregates thousands of listings to derive median values is computationally intensive and can be slow. The architectural solution is to target summary endpoints. Instead of performing local aggregations, the ingestion layer should query endpoints designed to return normalized benchmarks. For instance, a single request to an endpoint like GET /v1.1/client/city/investment can yield metrics such as airbnb_cap_rate, traditional_rental_income, and occupancy. This enables the frontend to render market health dashboards instantaneously without overburdening the application’s database.
This layer is particularly crucial for implementing the interactive heatmap feature. By fetching city-level averages, neighborhoods can be color-coded based on their performance, effectively guiding users toward the most profitable areas before they even select a specific listing.
Tier 2: The Property Object and Financial Core
This tier represents the heart of the application. While a standard MLS feed provides physical property characteristics, an investment API delivers essential financial performance data. The system should leverage endpoints like GET https://api.mashvisor.com/v1.1/client/property. This serves as a universal access point, allowing users to retrieve data using a street address, Mashvisor ID, or MLS ID, thereby ensuring flexibility regardless of how a deal is discovered. By submitting query parameters such as address, city, state, and zip_code, a request is triggered that returns far more than just a price.
It provides a detailed object containing calculated cash_flow, cap_rate, and rental_income for both Airbnb and traditional rental strategies, presented side-by-side. By ingesting this comprehensive object, the investment logic engine begins with a fully developed underwriting model rather than a blank slate. This allows developers to concentrate on building proprietary features, such as custom expense modeling, rather than fundamental calculations.
The distinction between "raw data" and "investment intelligence" becomes evident in the JSON response. Instead of mere physical specifications, the underwriting data is readily available:
  "mls_id": "937135",
  "ROI":
    "traditional_rental": 1835,
    "airbnb_rental": 397,
    "traditional_cap_rate": 1.81,
    "airbnb_cap_rate": -2.69,
    "roi_updated_at": "2026-01-25T08:09:11.000Z"
  ,
  "neighborhood":
    "name": "Little Bit of Country",
    "mashMeter": 29
This approach avoids the risks associated with incorrect metric calculations, which could erode user trust. A standard MLS feed offers physical attributes, whereas an intelligence-grade API provides the crucial underwriting data.
Tier 3: The Validation Layer
Trust is fundamentally built on verification. Users will be hesitant to accept ROI projections unless they can examine the comparable properties and aggregated data that underpin those figures. To establish a robust "Validation Layer," the architecture should integrate two synchronized endpoints:
-
Macro: Aggregated Analysis: The
GET /v1.1/client/rento-calculator/lookupendpoint is utilized to establish the market baseline. This serves as the engine for high-level projections. Because it operates dynamically across multiple geographic levels—city, neighborhood, zip code, or a specific street address—it enables the application to return pre-modeled financial metrics such as median rental income, occupancy rates, and cap rates in a single request. -
Micro: Dynamic Evidence: To ground these projections in tangible reality, the
GET/v1.1/client/rento-calculator/list-compsendpoint is layered in. This retrieves the actual Airbnb or Long-Term Rental (LTR) properties that were used in the analysis from the previous step.
The "Macro-to-Micro" advantage creates a seamless loop of trust by pairing high-level projections with granular evidence. By employing the synchronized rento-calculator endpoints, developers can deliver dynamic, street-level validation through a unified data structure, thereby enhancing both investor confidence and engineering efficiency.
The Logic Engine: Moving Beyond the API’s Raw Output
While APIs provide the essential raw data, the "engine" is what truly drives the application’s functionality. The most critical component of a custom architecture is the investment logic engine. This is the code that differentiates the platform from a mere data viewer. Many founders err by tightly coupling their frontend directly to the API response, displaying fields like airbnb_cash_flow directly to the user. This represents a significant missed opportunity. A production-grade architecture treats the API response as a baseline scenario.
Implementing the User Context Overlay
The investment logic engine should ingest these baseline values and then apply a "user context overlay." This overlay incorporates user-specific financing terms, their tax bracket, and their management preferences. For instance, an API might return a Cap Rate calculated based on an all-cash purchase. The application’s engine should then be capable of taking that Net Operating Income and dynamically calculating a Leveraged Internal Rate of Return (IRR) based on prevailing mortgage rates. This requires a stateless calculation service situated between the normalized data and the frontend.
The transformative power of this logic engine can be illustrated with an example: a property in Florida might exhibit a baseline IRR of 11% assuming an all-cash purchase. If a user then utilizes a financing option to apply a 25% down payment with a 6.8% mortgage rate, the engine should instantly recalculate that IRR to 17.4%, accurately accounting for the new debt service. This immediate transition from raw data to actionable insight is precisely why users are willing to pay for premium subscriptions.
This transformation constitutes the core of the software asset. The logic engine ingests the baseline "all-cash" data and outputs the "leveraged" reality:
  "baseline_irr": 0.11,
  "personalized_irr": 0.174,
  "user_context":  "down_payment": 0.25, "interest_rate": 0.068 ,
  "monthly_debt_service": 2150
By developing this logic layer, the application becomes insulated from direct API dependencies. Should the API source change, the proprietary algorithms for calculating IRR remain the intellectual property of the developer. This separation of concerns is vital for long-term scalability and the valuation of the software asset itself.
Solving Seasonality with Historical Data Analysis
One of the most complex challenges in real estate engineering is seasonality. A superficial assessment of rental income can be dangerously misleading. A property in a popular beach town might show negligible revenue in November but generate $15,000 in July. If an application only ingests the current month’s performance, it will provide a wildly inaccurate underwriting model.
To address this, the architecture must implement a "Time Series Analysis Layer." This layer interacts with historical performance endpoints to retrieve trend data over the preceding 12 to 36 months. When historical performance endpoints are queried, a dataset is returned containing monthly occupancy rates, average daily rates, and revenue figures. The architecture should not merely display this data as a chart; it should ingest this time-series data to compute a "Seasonality Index" for the property. By analyzing the month-over-month variance in occupancy, the system can assign a "Risk Score" to the asset. A property with consistent revenue is considered low risk, while one with high variance is deemed high risk. Presenting this calculated risk score to users adds significant value.
By analyzing the variance in occupancy month-over-month, the system can assign a risk score based on the historical time-series array:
  "property_id": "12345",
  "monthly_historical": [
    "month": "July", "rev": 8200, "occ": 0.94,
    "month": "Nov", "rev": 1200, "occ": 0.18
  ],
  "calculated_risk_index": "High (Seasonal)"
The Build vs. Buy Financial Argument
The decision to architect an application around an API like Mashvisor’s is fundamentally a financial one. The alternative—establishing an internal Data Engineering division—represents a substantial financial commitment, easily exceeding $150,000 per year in engineering salaries and infrastructure costs alone.
To better illustrate the trade-offs between engineering overhead and speed to market, consider the following comparison:
| Feature | Build Internal | Integrate API |
|---|---|---|
| Time to Market | 6-12 months | 2-4 weeks |
| Engineering | Dedicated Data Team required | Existing Backend team |
| Maintenance | Constant Scraper Updates | Managed Endpoints |
| Legal/Risk | High Legal Risk (Scraping) | Fully Licensed Data |
| Pricing | High/Unpredictable Capex | Fixed/Scalable Opex |
By adopting a "Buy" mindset rather than a "Build" approach, real estate data can be treated as a utility. This strategic shift allows the development team to focus on:
- Core Product Differentiation: Developing unique features and user experiences that set the application apart.
- User Experience Optimization: Enhancing the interface and workflow for maximum usability and engagement.
- Proprietary Logic Development: Creating advanced algorithms and analytical tools that leverage the foundational data.
- Scalability and Performance Tuning: Ensuring the application can handle increasing user loads and data volumes efficiently.
Monetizing the Intelligence Layer: Selling Insight Over Information
Generic real estate applications often struggle with monetization because property search has become a commoditized service. In contrast, investment-focused applications possess powerful revenue levers because they sell financial certainty and actionable insights. The monetization strategy should directly reflect the application’s data architecture.
The Pro Subscription: Gating the Intelligence Layer
The most effective monetization model is a value-based paywall. The "visual layer" (maps) and "inventory layer" (listing specifications) can be used to drive top-of-funnel engagement and encourage user sign-ups. Once a user attempts to access the "intelligence layer"—comprising pre-calculated cap rates, cash-on-cash returns, and logic-engine-driven calculators—they are prompted to upgrade to a Pro Tier. By gating the Mashvisor-powered financial objects, revenue generation is directly tied to the most valuable data points within the application’s stack.
The Enterprise Tier: The Validation and Risk Premium
For institutional investors or high-volume buyers, trust necessitates comprehensive evidence. The "validation layer" can be monetized separately. This tier provides access to:
- Bulk Data Exports: Enabling large-scale analysis and integration into existing systems.
- API Access: Allowing programmatic access to curated datasets for custom applications.
- White-Label Solutions: Offering branded versions of the platform for enterprise clients.
- Detailed Property-Level Underwriting Reports: Providing in-depth financial analyses for specific assets.
The High-Intent Lead Generation Model
Rather than selling generic leads to any real estate agent, a more effective approach is to route "Investment-Ready" leads. A user who has spent considerable time adjusting mortgage rate sliders within the logic engine is demonstrably a high-intent buyer. By tagging users based on the specific ROI thresholds they are targeting, they can be connected with investment-savvy realtors or lenders who are willing to pay a premium for qualified, data-driven prospects.
Conclusion
The current opportunity in PropTech is not about achieving sheer volume; it is about delivering significant value. By pivoting from a generic search portal to a specialized investment platform, developers can address more complex problems for a more affluent audience. With the right architecture, underpinned by robust data APIs like Mashvisor, it is possible to build a product that transcends simply showing users a house; it can illuminate their financial future. Technology is no longer the primary impediment. The tools now exist to develop such applications within months rather than years. The only remaining barrier is effective execution.
Ready to Build the Next Generation of PropTech?
Do not let data fragmentation hinder your launch timeline. Join the ranks of founders and developers who are leveraging Mashvisor’s infrastructure-grade API to power their sophisticated investment engines. Book a brief introductory call to map out your architecture and data stack.

